
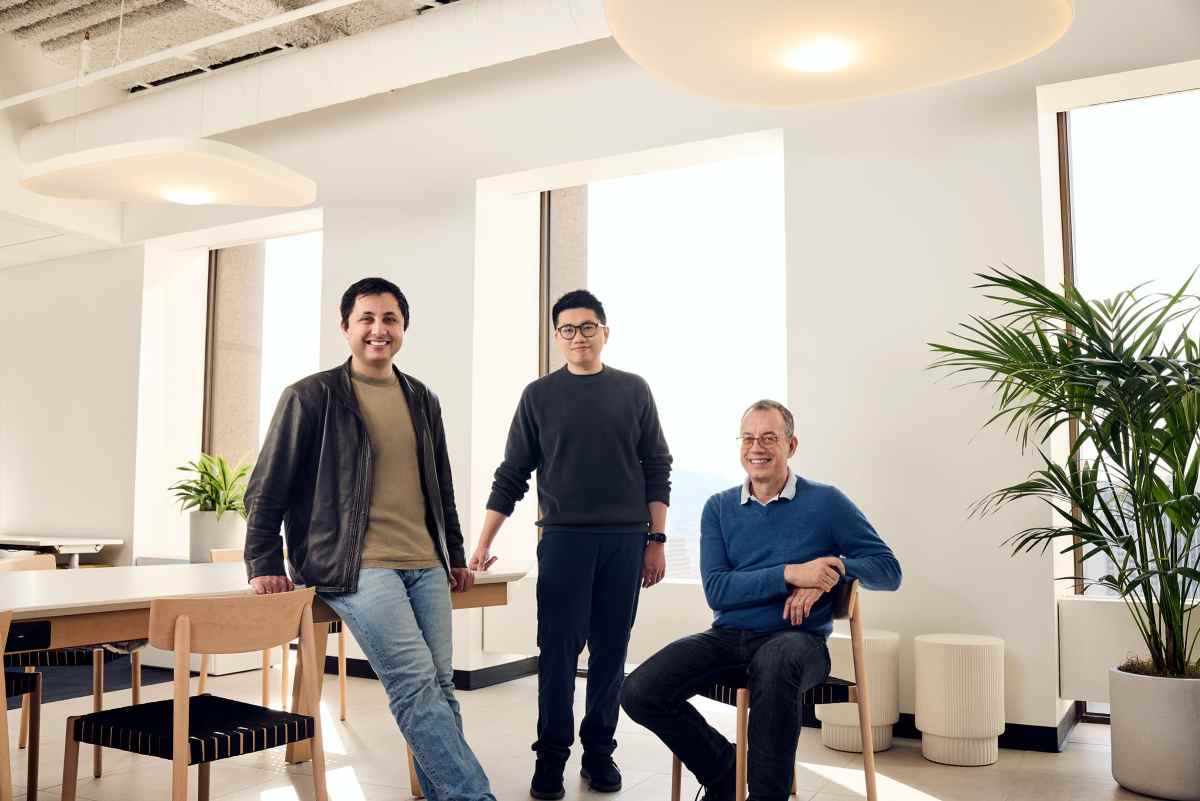
Arena, founded in 2023 as a research project at the University of California, Berkeley to crowdsource AI model rankings, announced Thursday that it has raised $200 million in a Series B round at a valuation of $3.1 billion.
This comes after the company announced in June that its annual run-rate revenue reached $100 million.
The round was led by Lightspeed Venture Partners and Khosla Ventures, with participation from Salesforce Ventures, 01 Advisors, Dell Technologies Capital, Endeavor Catalyst, a16z, Felicis and others. Arena previously announced a $150 million Series A in January at a post-money valuation of $1.7 billion. Annual revenue at the time was $30 million. In other words, the valuation has nearly doubled in about 10 months.
Arena provides a crowdsourcing platform that is free for consumers to use. People enter prompts or request vibe-coded projects and rate which model is better. Arena claims tens of millions of visitors per month.
Last September, the company announced a commercial product, AI Evaluations, a service that provides model labs and enterprises with detailed performance analysis based on community feedback. The timing was perfect. This year, AI Lab realized that their model was a benchmark test for games and found a way to get a good score without actually getting one. At the same time, companies were looking for help determining the best model for their internal needs, rather than relying solely on standardized benchmarks.
“AI is advancing faster than our ability to evaluate, and static benchmarks no longer work once we realize our models are being tested,” the company said in its funding announcement. “The world needs a neutral third party to measure how secure and regulated AI really is once it’s in the hands of real people. Arena is stepping into that role today,” it added.
To that end, Arena has also added a new category to the leaderboard called Alignment. Here, we rank models based on issues such as incorrect actions (performing actions that were not requested). False attribution (falsely crediting a false source statement or fact). and what it calls “deceptive completion” (the lie that you completed a task you didn’t do).
OpenAI’s set of models currently sits at the top of the preliminary alignment leaderboard, with Claude Opus 5.5 and Claude Fable in 6th and 9th place, respectively.
If you make a purchase through links in our articles, we may earn a small commission. This does not affect editorial independence.
