
If AI Labs’ PrismML hasn’t caught your eye already, you should. It’s not because we’ve raised a lot of money (we haven’t raised one yet; our seed round is only $22.25 million). Because there’s technical thinking involved and technology being developed that has the potential to change industries.
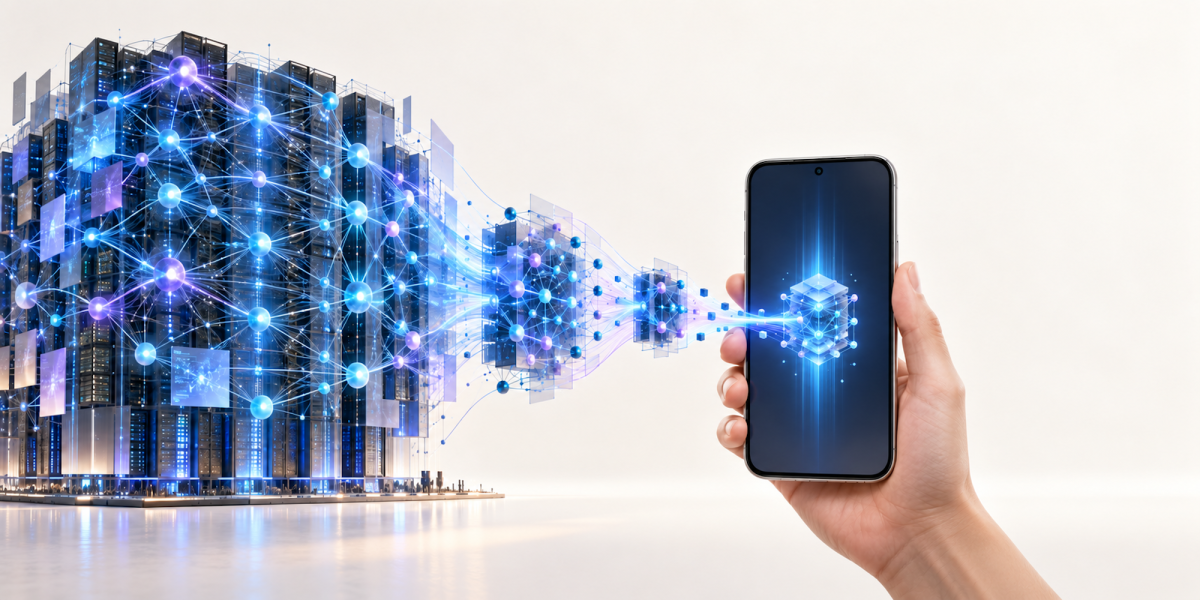
At PrismML, we believe that large language models that provide capable, high-performance inference don’t actually need to be large.
We have made the inference model small enough to fit on a PC or smartphone. (There are even rumors that the company is in talks with Apple, but CEO Babak Hassibi declined to comment on that to TechCrunch.)
On Thursday, PrismML released the latest edition of its model family, the Bonsai 2 27B. It compresses Alibaba’s widely used open source model, Qwen3.8 27B, to 5.9 GB. It’s small enough to fit into a PC or even a high-end smartphone. There is a 9x to 10x memory reduction compared to the original memory.
PrismML was founded by a group of Caltech researchers and led by Hassibi, a Caltech professor and compression technology expert. The startup also has Ion Stoica as an advisor. Stoica is a co-founder of Databricks (and other companies) and director of Berkeley’s famous Sky Computing Lab, which has spawned many technologies and startups from Letta to SGLang.
PrismML is also backed by investors Khosla Ventures, Cerberus Capital, and Caltech.
This startup is not the only one working on LLM compression technology. One of them is Multiverse Computing, founded by a distinguished professor at Spain’s Donostia International Physics Center. (And Multiverse Computing raised a ton of cash.)
But Hassibi says PrismML’s compression technology is unique because its LLM loses virtually no performance compared to the original. Bonsai 2 matches 98% of Qwen’s total benchmark score. This is an increase from the 95% match rate for the first Bonsai released a few months ago in March. Its original model has already been downloaded more than 11 million times, and PrismML’s smaller model has been downloaded an additional 2.6 million times, the company said.
This shows that PrismML’s compression results are improving with each release. Whether we can reach 100% benchmark performance parity remains to be seen. Hassibi says compression is always likely to have some effect.
Still, full benchmark equivalence is pretty academic anyway. LLM is not very accurate in its uncompressed form, and the benchmark does not fully reflect real-world tasks, so a 2% drop can have a significant impact on the model’s performance in real-world use. (Additionally, the surrounding software (the harness the model runs inside of) is also very important when it comes to accuracy.)
PrismML says it accomplishes this by reducing the “weights” that make up the model. Weights are essentially information that a model learns and stores during training. Typically, each weight requires 16 bits. PrismML’s approach, called “ternary” weights, simplifies it to three: +1, -1, or 0. Your model will take up much less space because you store much smaller values for each weight. (For more information on compression techniques, please see this project’s Hugging Face page.)
The startup’s next goal is to apply this compression technique to even larger models. “The next model that we’re going to release, hopefully in the next few months, is going to be in the range of hundreds of billions of parameters, and we expect it to be easier to keep the intelligence there,” Hashibi told TechCrunch.
As the size of the model increases, “there is more room to compress the model without losing intelligence. So I would just say that the general trend is that the larger the model, the easier it is to reach 100%,” he added.
Stoica says he is excited about this technology because it allows users to run advanced models on their devices. “The intelligence is immediately available. It also runs on devices you’ve already purchased, so it’s free. And it’s private, because you don’t send it to the cloud.”
If you make a purchase through links in our articles, we may earn a small commission. This does not affect editorial independence.
