
AI Labs is staking its reputation on model benchmarking, a supposedly neutral and accurate rating system designed to measure whether one AI product is better than another.
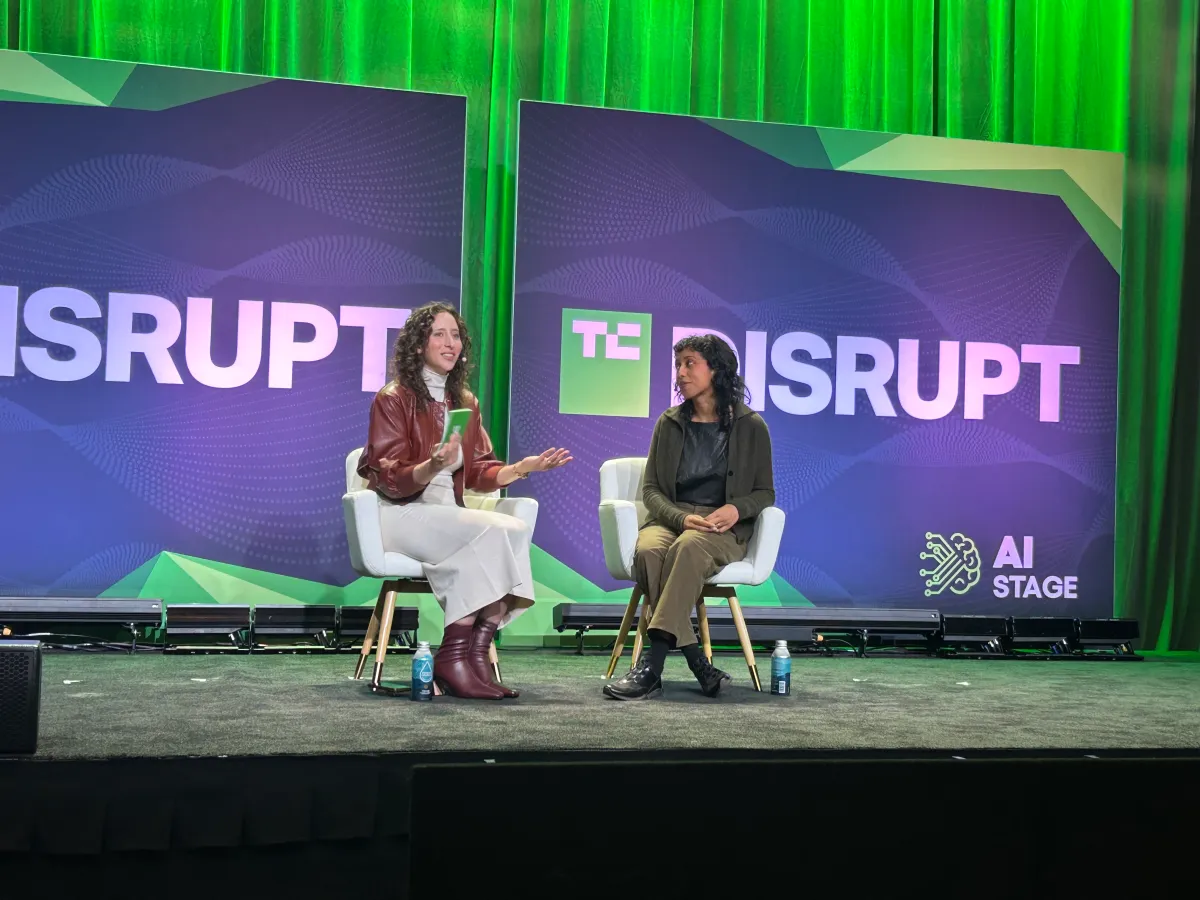
But the methodology behind these ratings is complex and still maturing, Hugging Face Chief Policy Officer Irene Solaiman said in a discussion at TechCrunch Disrupt last week. If the industry relies on testing in the future, testing must be integrated into a more coherent science.
With that in mind, can we trust the currently released tests?
“Trust is a very heavy word,” Solaiman says. “One of the important parts in terms of whether you can trust the results is whether you can reproduce the evaluation results; do you have the necessary level of access to the model itself? This is where open weights can be of great help,” she added.
The reproducibility of model evaluation has long been one of the most vexing aspects of benchmarking and remains a topic of significant debate in the industry.
Apart from the validity of an individual test, an additional question is how the test compares to other assessments.
“They’re evolving sciences, and we don’t know how to meaningfully compare them to each other,” Solaiman says.
“They start to become ineffective relatively quickly. We don’t have as thriving an ecosystem as we need,” she added. “There is currently a growing desire for a built-in rater ecosystem, but there needs to be more standardization around the qualifications that determine who is an effective rater across which tasks.”
The idea of embedded evaluators, which place supposedly “neutral” third-party observers within AI organizations, has become popular in recent months as AI labs grapple with a rash of safety incidents that have fueled concerns about the technology’s potential harm. Hug Face was famously the target of those incidents.
Instead of aggressive government regulation to identify and alleviate model safety concerns, laboratories have promoted third-party solutions. However, questions remain about how neutral and effective those evaluators really are. Anthropic’s decision to hire Accenture as its first evaluator sparked considerable backlash, with some critics deriding the idea that the consulting firm was qualified to perform the task at hand.
Evaluation is now moving from simply testing the model itself to testing the entire system around the model, including harnesses and agents. Soleiman shared that the harness (i.e. the tool the user is using to access the model) is particularly relevant to model performance, and a weaker model with a better harness can easily outperform a frontier model.
“Evaluating agents is very difficult and very expensive,” Solaiman says. “We just have more model ratings. … We don’t have as many harness ratings, but we’re developing better general agent ratings because a lot of people are getting value out of it,” she added.
In other words, there is currently more or less open space for evaluation, and if benchmarking is to continue to be seen as a useful tool for industry leaders, a more unified industry-wide approach that gets everyone on the same page may be needed.
If you make a purchase through links in our articles, we may earn a small commission. This does not affect editorial independence.
